- AI & LLM
- AI Strategy
- Software Architecture
- Product Development
Adding AI to Your Product: A Practical LLM Integration Playbook
Most AI projects stall between the demo and production. This playbook covers where LLMs actually pay off, the guardrails real users need, and how to run a pilot that proves value in six weeks.
 Arsalan Sadiq 5 min read
The demo always works. Someone pastes a few documents into a chatbot, asks a question, and the room gets excited. Then the project heads toward production and meets the questions nobody asked during the demo. What happens when it's wrong? Who can see the customer data? Why is the bill four times the estimate?
I've helped teams get across that gap. This is the playbook I use, written for the people who fund and own these projects, with enough detail for the people who build them.
Where does AI actually pay off?
Large language models are good at a particular kind of work: reading, summarizing, classifying and drafting language. They're not good at being a source of truth, doing exact arithmetic, or making decisions nobody can explain.
The use cases that pay off usually share three traits:
- High volume, low stakes per item. Triaging support tickets, tagging documents, drafting first replies.
- A person stays in the loop. The model drafts and a person approves. Productivity goes up without handing over responsibility.
- Your own data makes it better. Answers grounded in your policies, contracts or product documentation rather than general internet knowledge.
If a proposed use case has none of these, be sceptical.
What's hype and what's real?
| What you'll hear | What I've seen in practice |
|---|---|
| "Just fine-tune a model on our data" | Retrieval (RAG) usually gets you further, faster and for less |
| "AI will replace the team" | It removes repetitive work, and people move to judgment calls |
| "Accuracy is a model problem" | It's mostly a data and prompt problem, and you can measure it |
| "We need the biggest model" | Smaller models handle many tasks at a fraction of the cost |
| "It's a weekend project" | The prototype is. Production needs evaluation, security and monitoring |
What does a sound architecture look like?
For most business use cases I start with retrieval-augmented generation, or RAG. Your documents are split into chunks and indexed for search. When a user asks a question, the most relevant chunks are sent to the model with it. The model answers from your content, and you can show the sources.
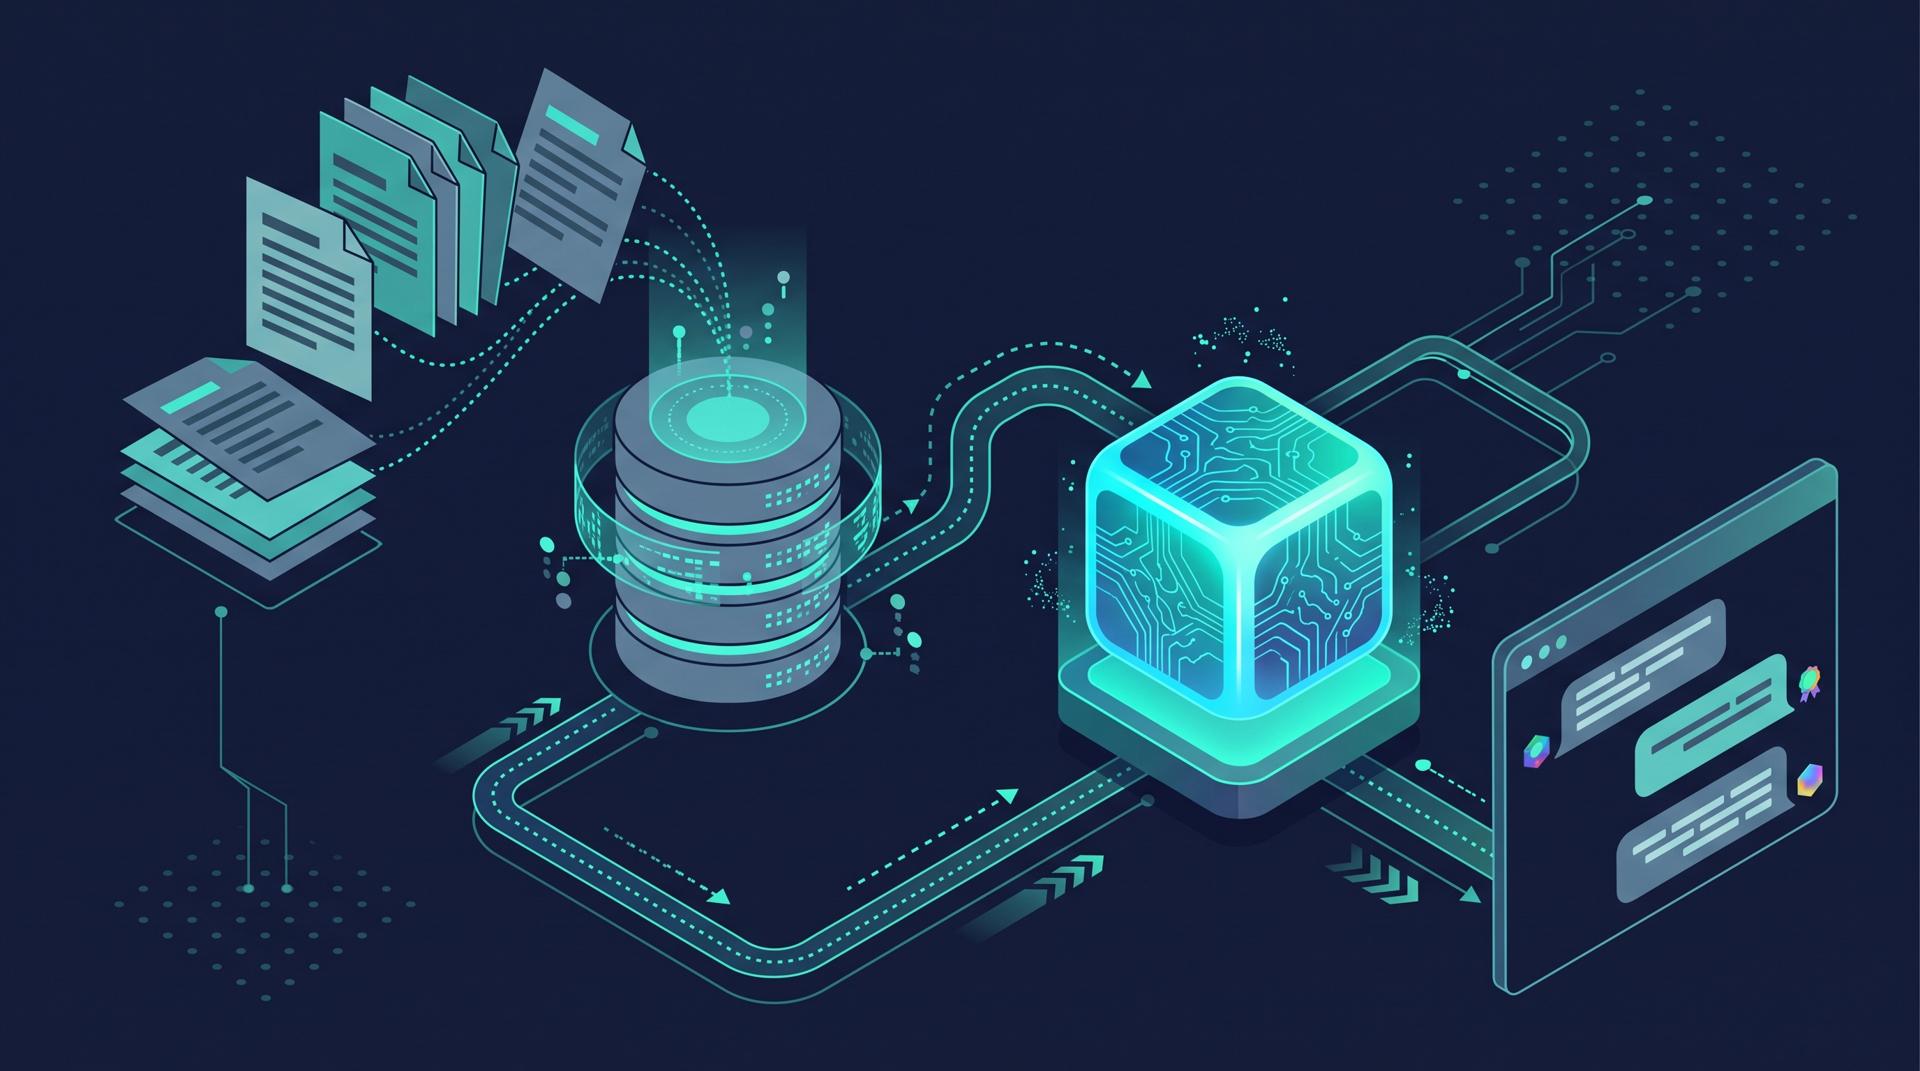
The parts aren't exotic:
- Ingestion. Pull documents from where they live, clean them and split them sensibly.
- Search. A vector index, often combined with plain keyword search, which still matters for product codes and names.
- The model call. A carefully written prompt with the retrieved context, and clear instructions for what to do when the answer isn't there.
- Output handling. Validation, citations and logging.
- Evaluation. A set of real questions with known good answers, run on every change.
Most teams skip the fifth part. It's also the only one that tells you whether the thing works.
How do we stop it going wrong?
Guardrails are what separate a demo from a product. These are the five I insist on.
Ground every answer. Tell the model to answer only from the context it's given, and to say so when it can't. Show sources so users can check.
Validate structured output. If the model returns data your code acts on, check it against a schema before using it. Never assume free text has the right shape.
import { z } from 'zod';

const TicketTriage = z.object({
  category: z.enum(['billing', 'technical', 'account', 'other']),
  urgency: z.enum(['low', 'normal', 'high']),
  summary: z.string().max(280),
});

export function parseTriage(raw: string) {
  let data: unknown;
  try { data = JSON.parse(raw); } catch { data = null; }
  const result = TicketTriage.safeParse(data);
  // Anything that doesn't fit goes to a person instead of a guess.
  return result.success
    ? result.data
    : { category: 'other', urgency: 'normal', summary: 'Needs manual review' };
}
Protect the data. Know which provider sees what, where it's processed, and whether it's used for training. Strip personal information you don't need. Canadian companies should check their obligations under PIPEDA and provincial privacy laws. In the US, sector rules such as HIPAA may apply.
Limit what it can do. If the model can call tools or take actions, give it the smallest set of permissions possible, and require a person to confirm anything that changes data or spends money.
Watch it in production. Log prompts, responses, response times and cost. Read a sample of real answers every week. Users will find failures your test set missed.
How do we keep costs under control?
LLM costs grow with the amount of text you send and receive, so most savings come from sending less.
- Retrieve fewer, better chunks instead of filling the context window
- Use a smaller, cheaper model for simple steps like classification, and save the larger one for where it earns its cost
- Cache answers to questions that come up again and again
- Set per-user and per-day limits before launch, not after the first surprising invoice
Estimate the cost per task early. "Cost per resolved ticket" is a number a finance team can work with. "Tokens per month" isn't.
How do we prove it's worth it?
Run a short, honest pilot with a success measure everyone agrees on before you start.
| Week | Focus | What you have at the end |
|---|---|---|
| 1 | Choose one use case and one metric | A one-page brief everyone has signed off on |
| 2 | Collect real examples | 50 to 200 test questions with good answers |
| 3 | Build the first working version | An internal-only prototype |
| 4 | Measure and improve | Accuracy and cost per task on the test set |
| 5 | Put it in front of real users | A limited rollout with feedback |
| 6 | Decide | Scale it, change it or stop |
Stopping is a valid result. A pilot that shows a use case won't work has saved you a much bigger bill.
Where to begin
Pick the one process in your business where people spend hours reading and summarizing text, where mistakes can be caught and fixed, and where you can measure the before and after. That's your pilot.
If you'd like a second pair of eyes on a use case or architecture you're considering, book a short call. I'll tell you honestly whether I think it's a good fit for AI.
Views here are my own and don't represent any current or past employer or client. This is general information, not professional advice for your situation. Full disclaimer
Working on something similar?
I help businesses and founders design and build software like this. Book a free call or send a few details about your project.